Thursday, 08 October, 2026
XTDB meets kdb+
 James Henderson
I’ve recently been reading up on kdb+, after a few conversations with some interesting people piqued my interest. One thing that did strike me was the architectural overlap between kdb+ and XTDB - so, now that XTDB supports external sources (importing data from your existing data stores), I wondered: what would it take to get kdb+ market tick data feeding into XTDB?
The demo itself
The data model’s pretty simple: each sym becomes an XTDB entity, and each tick a new version of it - valid from the tick’s time until the next tick for that sym arrives.
The tickerplant publishes a trade table, in kdb+tick’s usual shape:
trade:([] time:`timespan$(); sym:`g#`symbol$(); price:`float$(); size:`int$())
Here’s how each of its columns lands in XTDB’s trade table:
| kdb+ column | e.g. | XTDB column |
|---|---|---|
time | 0D14:30:01.250000000 | _valid_from1 |
sym | `AAPL | _id |
price | 187.42 | price |
size | 200 | size |
(time and sym are kept as columns too, so you can still query them by their kdb+ names.)
So, after a few ticks, AAPL’s history in XTDB looks something like this - each tick is valid until the next one for that sym supersedes it, and the latest is valid indefinitely:
_id | price | size | _valid_from | _valid_to |
|---|---|---|---|---|
AAPL | 187.42 | 200 | 2026-10-08T14:30:01.250Z | 2026-10-08T14:30:01.300Z |
AAPL | 187.51 | 50 | 2026-10-08T14:30:01.300Z | 2026-10-08T14:30:01.350Z |
AAPL | 187.38 | 12000 | 2026-10-08T14:30:01.350Z | null |
So a plain SELECT gives you the current book, and XTDB’s temporal SQL gives you the book as of any instant you like.
SELECT _id AS sym, price, size FROM trade ORDER BY _id;
sym | price | size |
|---|---|---|
AAPL | 187.38 | 12000 |
GOOG | 151.07 | 300 |
MSFT | 299.84 | 75 |
SELECT _id AS sym, price, size
FROM trade FOR VALID_TIME AS OF TIMESTAMP '2026-10-08T14:30:01.320Z'
ORDER BY _id;
sym | price | size |
|---|---|---|
AAPL | 187.51 | 50 |
GOOG | 150.92 | 120 |
MSFT | 299.97 | 400 |
Getting it running
We started the demo by starting XTDB and then the JVM-based tickerplant.
Once they were both started, we attached the kdb+ ticks to XTDB as an external source:
ATTACH DATABASE ticks WITH $$
  log: !Local
    path: modules/kdb/build/demo-state/ticks-log

  storage: !Local
    path: modules/kdb/build/demo-state/ticks-storage

  externalSource: !Kdb
    port: 5010
    indexer: !Ticks {}
$$;
With this, XTDB subscribes to the kdb+ tickerplant, and mirrors all the tick data into XTDB as a new ‘ticks’ database.
We can now query the ticks database using XTDB’s SQL:2011 standard temporal SQL:
-- the book now: the latest tick per sym
SELECT _id AS sym, price, size, _valid_from
FROM trade
ORDER BY _id;

-- AAPL's history, newest first - each tick is valid until the next one
SELECT price, size, _valid_from, _valid_to
FROM trade FOR ALL VALID_TIME
WHERE _id = 'AAPL'
ORDER BY _valid_from DESC
LIMIT 5;

-- the book as it stood five seconds ago
SELECT _id AS sym, price, _valid_from
FROM trade FOR VALID_TIME AS OF CURRENT_TIMESTAMP - INTERVAL 'PT5S'
ORDER BY _id;
Combining this with watch, we can create a simple screen to see the ticks coming in in real time:
We’re looking for Design Partners! If you’ve got data in kdb+, and would like to:
- query it using XTDB’s SQL:2011 standard temporal SQL
- store your kdb+ historical data in cheaper cloud object storage, while still keeping it accessible for queries
- access it through PostgreSQL/ADBC ecosystem tooling - BI tools, client drivers, etc
Let us know! We’d love to work with you to make this a reality.
Architectural similarities between kdb+ and XTDB
Back to that architectural overlap, then - in short:
- Both use a single-threaded writer to process an incoming queue of new events
- Both maintain an in-memory index of the most recent data
- Both periodically write out historical data to disk (or object storage) in a columnar format.
Here’s my (rudimentary) understanding of kdb+‘s architecture:
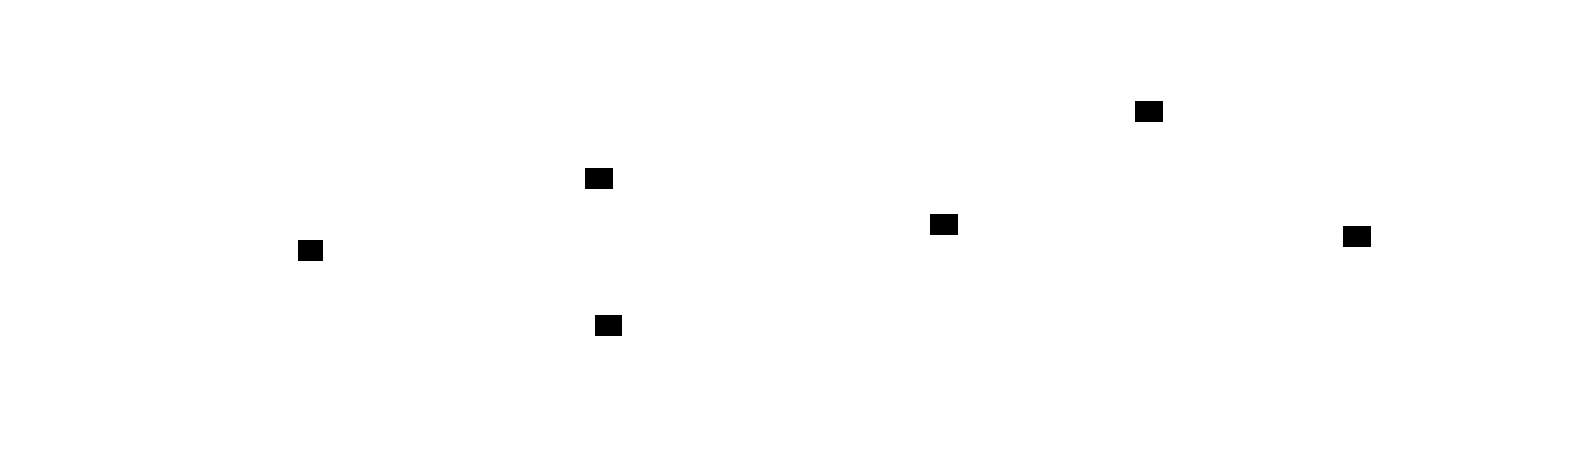
- A feed handler publishes updates - trades, quotes, etc - to the tickerplant.
- The tickerplant appends each update to its log on disk, so that the day can be replayed after a restart.
- It then publishes each update to its subscribers - here, the real-time database (RDB), which holds today’s data in memory.
- At end of day, the RDB writes the day’s data out to the historical database (HDB) - date-partitioned, columnar files on disk - and clears down, ready for the next day.
- Queries go to the RDB for today’s data, and to the HDB for history - often through a gateway that routes between the two.
For comparison, here’s XTDB’s architecture:
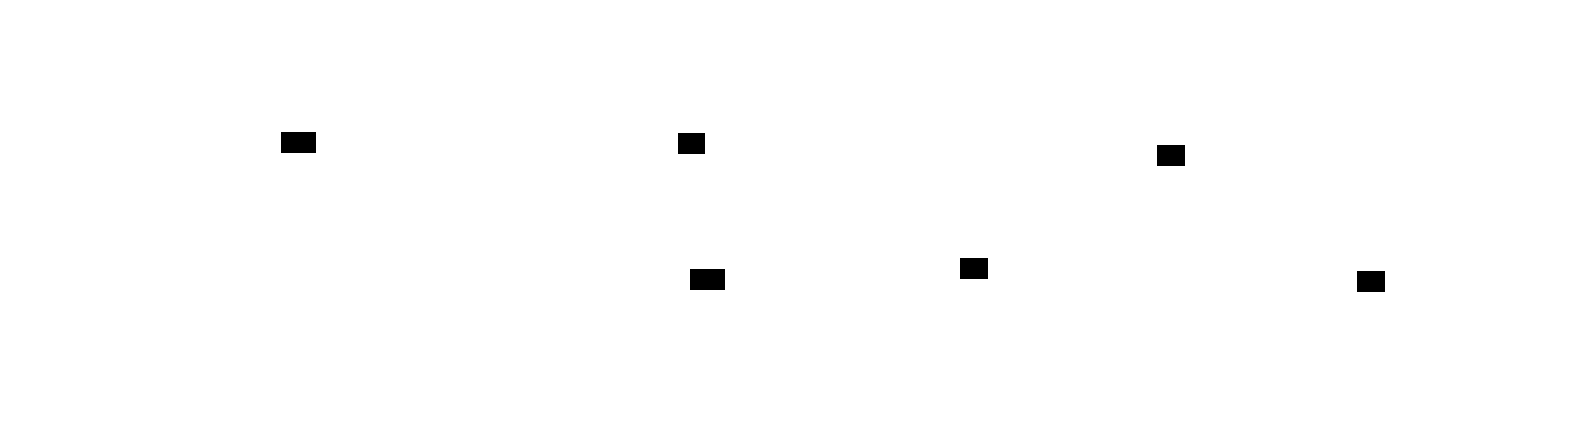
- Transactions come into XTDB from two sources:
- For XTDB databases, clients submit SQL DML transactions to the log.
- For external sources (new in v2.2), the external source drives the indexer directly, bypassing our log (because the upstream system already orders the events for us).
- The indexer applies each transaction, in order, to its in-memory ‘live index’. It’s a single writer: in v2.2, one node leads the indexing and the others follow along (more on that in our leadership election post).
- Once the live index has built up enough rows, it’s flushed to object storage as Apache Arrow files. In the background, compaction then merges these into larger, sorted files over time.
- Queries read recent data from the live index and history from object storage, combining the two into one consistent view - each node caching the files its queries need locally.
Side by side:
| kdb+tick | XTDB | |
|---|---|---|
| Incoming events | the tickerplant (and its log) | the transaction log |
| Single writer | the RDB | the indexer |
| Recent data, in memory | the RDB | the live index |
| History, columnar | the HDB, on disk | Arrow files, in object storage |
| Queries | q, against the RDB and HDB | SQL, across the live index and object storage |
…and the differences
It’s not all the same, of course - as I understand it, the main differences are:
- Time: kdb+ has one notion of time - the tick’s
time. XTDB is bitemporal - it records both when a fact was true (‘valid time’) and when we learned about it (‘system time’) - so late or corrected ticks can be recorded as corrections, without losing what we originally believed. - Where history lives: the HDB is date-partitioned files on disk; XTDB stores an LSM tree of Arrow files in shared object storage (e.g. AWS S3), with compute separated from storage. So you can spin up more query nodes to scale out, or to isolate different groups of users from each other. The partitioning strategy of the LSM tree naturally shards time-series data into buckets - for more detail on how this works, see the third part of my ‘Building a Bitemporal Index’ trilogy: ‘Storage’.
- When data moves to history: kdb+ rolls the day over at end of day; XTDB flushes continuously, and compacts as it goes.
- Query language: q, vs SQL - over the Postgres wire protocol, which brings with it the BI tools, drivers and the rest of the Postgres ecosystem.
- What each is tuned for: kdb+ is built for very high-throughput time-series analytics; XTDB is a general-purpose database. We wouldn’t claim kdb+ speeds - which is exactly why we’d want XTDB alongside kdb+ rather than in place of it.
External sources
External sources are new to XTDB in v2.2, and are a key part of our vision for XTDB as a federated data-mesh.
Organisations have existing data in a variety of different data stores. We recognise that it’s just not practical in most cases to migrate all that data into XTDB. So, through external sources, we’re taking XTDB to your existing data instead.
With external sources, XTDB subscribes to your data source, mirrors the data into XTDB as a new ‘database’, and allows you to query it using XTDB’s bitemporal SQL. In XTDB, it’s possible to query across multiple databases in a single query, so you can join all these data sources together.
We’re initially releasing with support for PostgreSQL and Kafka - but this is a pluggable interface, so do let us know what you’d like to import.
In both PostgreSQL and Kafka, you can also supply your own indexer (a mapping function to transform Postgres rows/Kafka messages into XT documents) as the data comes in. Particularly for Kafka, you could consider this new functionality as the basis of an event-driven architecture.
What’s next?
So, what would it take to get this from a PoC to something you’d run in production? From where I’m sitting:
- resilience of the kdb+ → XTDB connection - the demo drops data while the connection isn’t active.
- ingestion performance at kdb+ levels, so that we’re never a ‘slow subscriber’. I’d hope we’re not far off, but kdb+ is known to be an absolute beast at this.
- backfill from the HDB - the demo only picks up data from the point you attach.
This is where we’d love your help: if you’ve got data in kdb+ and this sounds interesting, we’re looking for design partners and early adopters to help shape what it looks like and kick the tyres. It needn’t be onerous - at a minimum, it’s keeping in touch over IM, and, if you’ve got the time, the odd call.
If you’ve any questions or thoughts, please do get in touch - hello@xtdb.com, or come and join us on our Discord.
Until next time!
James
Footnotes
-
kdb+tick sends
timeas a timespan - time since midnight - so XTDB adds it to the transaction’s date (stepping back a day for any ticks published just before midnight). ↩